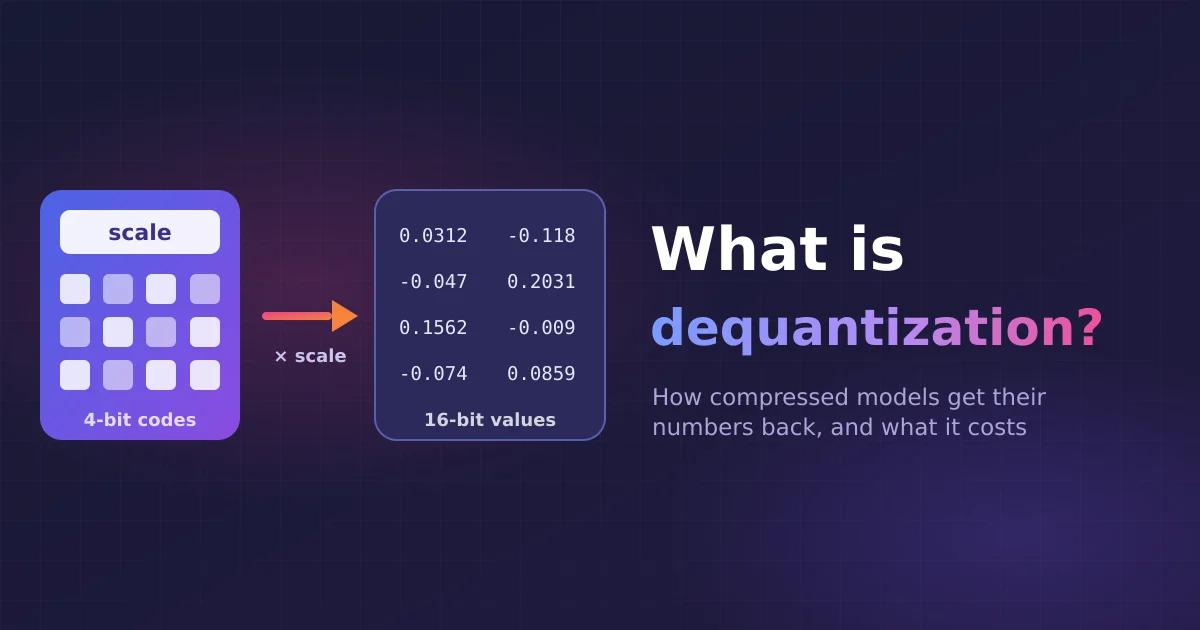
What is dequantization?
How quantized models store their weights, what dequantization does, why it costs speed, and how Matricxon multiplies compressed weights without unpacking the whole model.
Read more → BytePenny
Notes and guides on running AI on your own hardware.
How quantized models store their weights, what dequantization does, why it costs speed, and how Matricxon multiplies compressed weights without unpacking the whole model.
Read more →Do you need a graphics card to run a language model? What a GPU really speeds up, where a CPU holds its own, and how to choose for your own setup.
Read more →MCP is an open standard that lets AI apps use tools and data through one common plug. What it is, how a tool call works, and how to use it safely.
Read more →Retrieval-augmented generation lets a language model answer from your own documents. How RAG works step by step, how reranking improves it, and why it is slow on a CPU.
Read more →Language models guess at math; Wolfram|Alpha computes it. What the Wolfram MCP server is, what its tools do, why it makes math and facts reliable, and how to connect it.
Read more →No GPU? A modern CPU can run a useful language model. Why memory bandwidth decides speed, how to pick and tune a model, and the tricks Matricxon uses.
Read more →